

Intelligent Computing for Engineering | Volume 1, Issue 1: 30-42, 2026 | DOI: 10.62762/ICE.2026.187437
Abstract
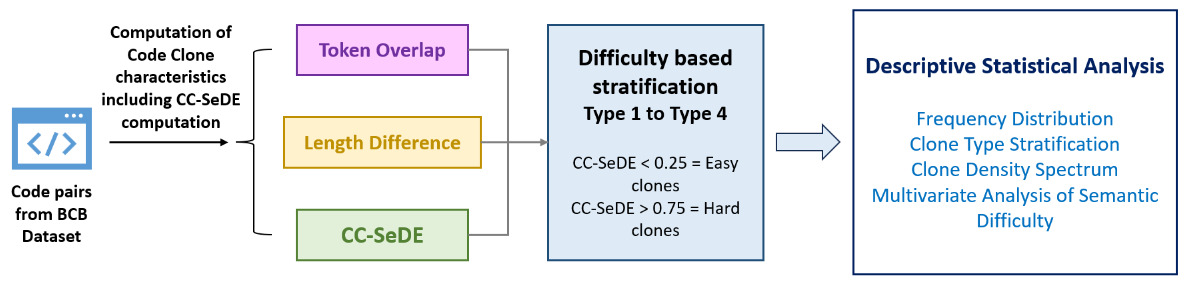
Code clone detection aims to identify duplicate code fragments within source code repositories. Existing models give every code pair in a dataset the same learning weight and ignore the fact that pairs differ in semantic complexity. This work introduces a parameter, the Code Clone Semantic Difficulty Estimator (CC-SeDE), to quantify the degree of semantic divergence between the two fragments of a code pair. Rather than treating semantic divergence as a direct proxy for classification difficulty, the approach provides a continuous measure that allows clone pairs to be characterized and stratified across the divergence spectrum. In the validation protocol the parameter is computed from token o... More >
Graphical Abstract