Self-supervised Segmentation Feature Alignment for Infrared and Visible Image Fusion


Article Information
Abstract
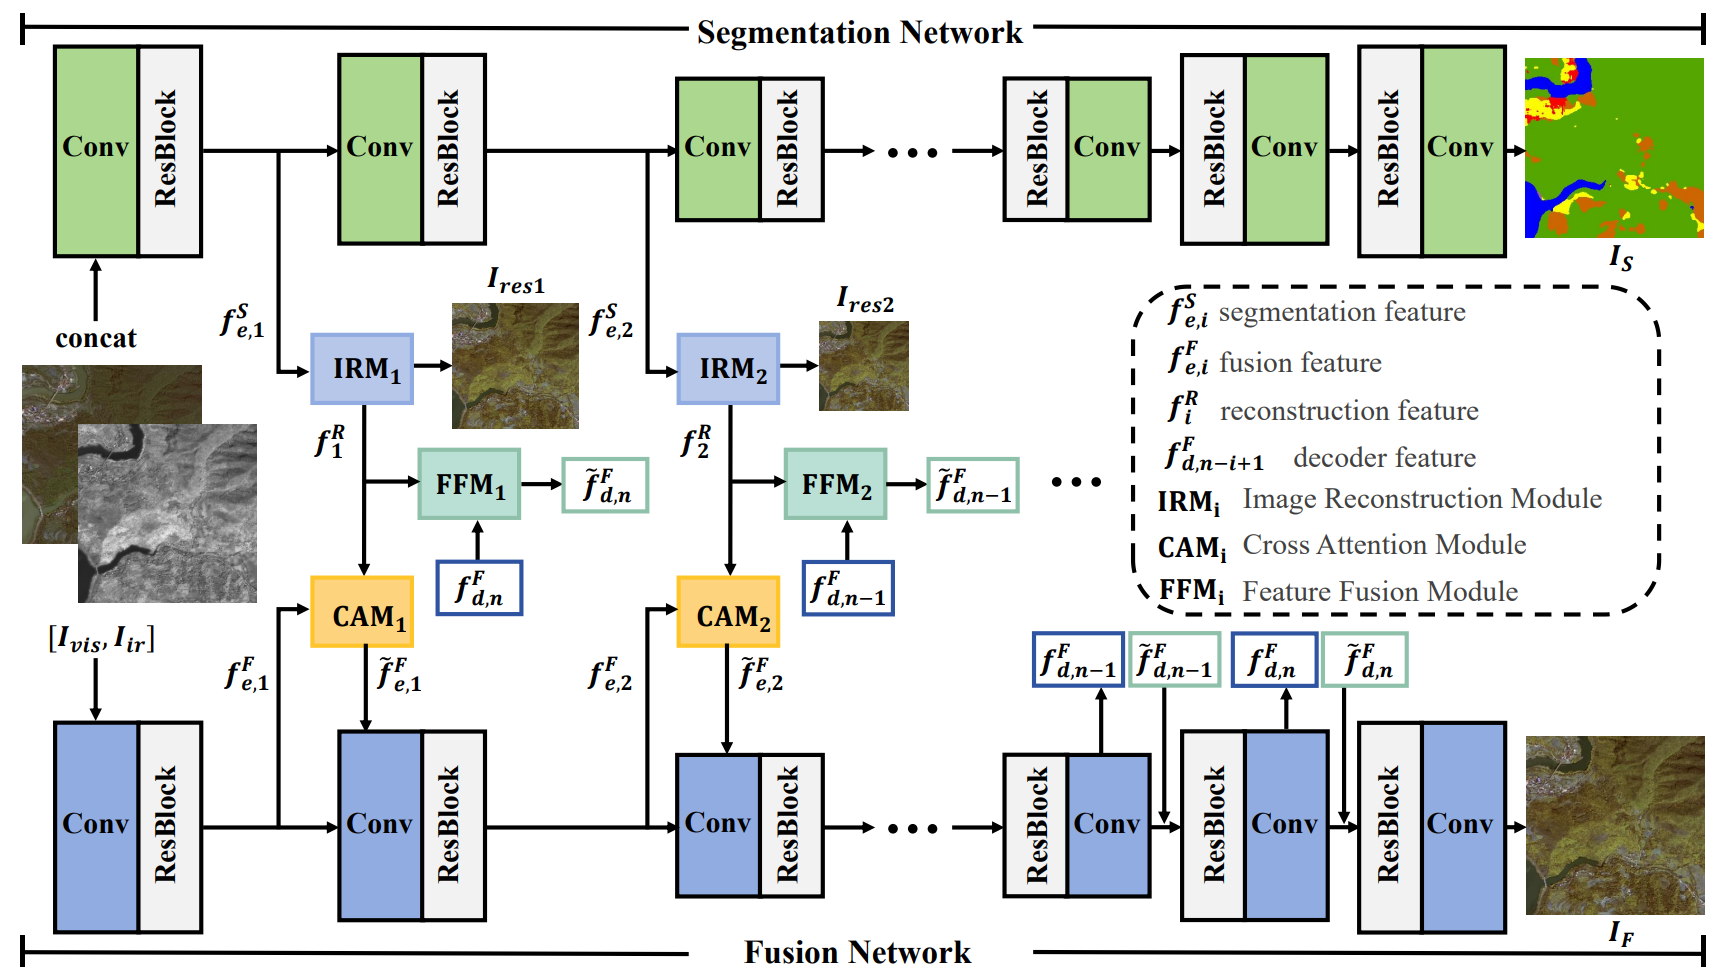
Existing deep learning-based methods for infrared and visible image fusion typically operate independently of other high-level vision tasks, overlooking the potential benefits these tasks could offer. For instance, semantic features from image segmentation could enrich the fusion results by providing detailed target information. However, segmentation focuses on target-level semantic feature information (e.g., object categories), while fusion focuses more on pixel-level detail feature information (e.g., local textures), creating a feature representation gap. To address this challenge, we propose a self-supervised segmentation feature alignment fusion network (SegFANet), which aligns target-level semantic features from segmentation tasks with pixel-level fusion features through self-supervised learning, thereby bridging the feature gap between the two tasks and improving the quality of image fusion. Extensive experiments on the WHU and Potsdam datasets show our method's effectiveness, outperforming the state-of-the-art methods.
Graphical Abstract
Keywords
Data Availability Statement
Funding
Conflicts of Interest
Ethical Approval and Consent to Participate
References
- Das, S., & Zhang, Y. (2000). Color night vision for navigation and surveillance. Transportation Research Record, 1708(1), 40--46.
[CrossRef] [Google Scholar] - Paramanandham, N., & Rajendiran, K. (2018). Multi sensor image fusion for surveillance applications using hybrid image fusion algorithm. Multimedia Tools and Applications, 77(10), 12405-12436.
[CrossRef] [Google Scholar] - Karim, S., Tong, G., Li, J., Qadir, A., Farooq, U., & Yu, Y. (2023). Current advances and future perspectives of image fusion: A comprehensive review. Information Fusion, 90, 185-217.
[CrossRef] [Google Scholar] - Qi, J., Liang, T., Liu, W., Li, Y., & Jin, Y. (2024). A Generative-Based Image Fusion Strategy for Visible-Infrared Person Re-Identification. IEEE Transactions on Circuits and Systems for Video Technology, 34(1), 518–533.
[CrossRef] [Google Scholar] - Li, H., Ding, W., Cao, X., & Liu, C. (2017). Image registration and fusion of visible and infrared integrated camera for medium-altitude unmanned aerial vehicle remote sensing. Remote Sensing, 9(5), 441.
[CrossRef] [Google Scholar] - Ruan, Z., Wan, J., Xiao, G., Tang, Z., & Ma, J. (2024). Semantic attention-based heterogeneous feature aggregation network for image fusion. Pattern Recognition, 155, 110728.
[CrossRef] [Google Scholar] - Xu, X., Wang, S., Wang, Z., Zhang, X., & Hu, R. (2021). Exploring image enhancement for salient object detection in low light images. ACM transactions on multimedia computing, communications, and applications (TOMM), 17(1s), 1-19.
[CrossRef] [Google Scholar] - Gao, Y., Ma, S., & Liu, J. (2023). DCDR-GAN: A densely connected disentangled representation generative adversarial network for infrared and visible image fusion. IEEE Transactions on Circuits and Systems for Video Technology, 33(2), 549-561.
[CrossRef] [Google Scholar] - Liu, R., Ma, L., Ma, T., Fan, X., & Luo, Z. (2023). Learning with nested scene modeling and cooperative architecture search for low-light vision. IEEE Transactions on Pattern Analysis and Machine Intelligence, 45(5), 5953-5969.
[CrossRef] [Google Scholar] - Aslantas, V., & Bendes, E. (2015). A new image quality metric for image fusion: The sum of the correlations of differences. AEU - International Journal of Electronics and Communications, 69(12), 1890-1896.
[CrossRef] [Google Scholar] - Jian, L., Yang, X., Liu, Z., Jeon, G., Gao, M., & Chisholm, D. (2021). SEDRFuse: A symmetric encoder–decoder with residual block network for infrared and visible image fusion. IEEE Transactions on Instrumentation and Measurement, 70, 1-15.
[CrossRef] [Google Scholar] - Han, Y., Cai, Y., Cao, Y., & Xu, X. (2013). A new image fusion performance metric based on visual information fidelity. Information Fusion, 14(2), 127-135.
[CrossRef] [Google Scholar] - Li, H., & Wu, X. J. (2018). DenseFuse: A fusion approach to infrared and visible images. IEEE Transactions on Image Processing, 28(5), 2614-2623.
[CrossRef] [Google Scholar] - Li, H., Wu, X.-J., & Durrani, T. (2020). NestFuse: An infrared and visible image fusion architecture based on nest connection and spatial/channel attention models. IEEE Transactions on Instrumentation and Measurement, 69(12), 9645-9656.
[CrossRef] [Google Scholar] - Ma, J., Yu, W., Liang, P., Li, C., & Jiang, J. (2019). FusionGAN: A generative adversarial network for infrared and visible image fusion. Information Fusion, 48, 11-26.
[CrossRef] [Google Scholar] - Ma, J., Xu, H., Jiang, J., Mei, X., & Zhang, X.-P. (2020). DDcGAN: A dual-discriminator conditional generative adversarial network for multi-resolution image fusion. IEEE Transactions on Image Processing, 29, 4980-4995.
[CrossRef] [Google Scholar] - Liu, J., Fan, X., Huang, Z., Wu, G., Liu, R., Zhong, W., & Luo, Z. (2022). Target-aware dual adversarial learning and a multi-scenario multi-modality benchmark to fuse infrared and visible for object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (pp. 5792-5801).
[CrossRef] [Google Scholar] - Tang, L., Yuan, J., & Ma, J. (2022). Image fusion in the loop of high-level vision tasks: A semantic-aware real-time infrared and visible image fusion network. Information Fusion, 82, 28-42.
[CrossRef] [Google Scholar] - Tang, W., He, F., & Liu, Y. (2023). YDTR: Infrared and visible image fusion via Y-shape dynamic transformer. IEEE Transactions on Multimedia, 25, 5413-5428.
[CrossRef] [Google Scholar] - Li, H., Wu, X.-J., & Kittler, J. (2021). RFN-Nest: An end-to-end residual fusion network for infrared and visible images. Information Fusion, 73, 72-86.
[CrossRef] [Google Scholar] - Li, J., Huo, H., Li, C., Wang, R., Sui, C., & Liu, Z. (2021). Multigrained attention network for infrared and visible image fusion. IEEE Transactions on Instrumentation and Measurement, 70, 1-12.
[CrossRef] [Google Scholar] - Zhang, Y., Liu, Y., Sun, P., Yan, H., Zhao, X., & Zhang, L. (2020). IFCNN: A general image fusion framework based on convolutional neural network. Information Fusion, 54, 99-118.
[CrossRef] [Google Scholar] - Ma, J., Tang, L., Xu, M., Zhang, H., & Xiao, G. (2021). STDFusionNet: An infrared and visible image fusion network based on salient target detection. IEEE Transactions on Instrumentation and Measurement, 70, 1-13.
[CrossRef] [Google Scholar] - Tang, L., Yuan, J., Zhang, H., Jiang, X., & Ma, J. (2022). PIAFusion: A progressive infrared and visible image fusion network based on illumination aware. Information Fusion, 83, 79-92.
[CrossRef] [Google Scholar] - Wang, D., Liu, J., Fan, X., & Liu, R. (2022). Unsupervised misaligned infrared and visible image fusion via cross-modality image generation and registration. arXiv preprint arXiv:2205.11876.
[Google Scholar] - Wang, Z., Bovik, A.C., Sheikh, H.R., & Simoncelli, E.P. (2004). Image quality assessment: from error visibility to structural similarity. IEEE Transactions on Image Processing, 13(4), 600-612.
[CrossRef] [Google Scholar] - Milletari, F., Navab, N., & Ahmadi, S.-A. (2016). V-Net: Fully convolutional neural networks for volumetric medical image segmentation. In Proceedings of the 2016 Fourth International Conference on 3D Vision (3DV) (pp. 565-571).
[CrossRef] [Google Scholar] - Crum, W.R., Camara, O., & Hill, D.L.G. (2006). Generalized overlap measures for evaluation and validation in medical image analysis. IEEE Transactions on Medical Imaging, 25(11), 1451-1461.
[CrossRef] [Google Scholar] - Kline, D.M., & Berardi, V.L. (2005). Revisiting squared-error and cross-entropy functions for training neural network classifiers. Neural Computing and Applications, 14, 310–318.
[CrossRef] [Google Scholar] - Zhang, X. (2021). Deep learning-based multi-focus image fusion: A survey and a comparative study. IEEE Transactions on Pattern Analysis and Machine Intelligence, 44(9), 4819-4838.
[CrossRef] [Google Scholar] - Shelhamer, E., Long, J., & Darrell, T. (2016). Fully Convolutional Networks for Semantic Segmentation. IEEE Transactions on Pattern Analysis and Machine Intelligence, 39(4), 640-651.
[CrossRef] [Google Scholar] - Xu, H., Wang, X., & Ma, J. (2021). DRF: Disentangled Representation for Visible and Infrared Image Fusion. IEEE Transactions on Instrumentation and Measurement, 70, 1-13.
[CrossRef] [Google Scholar] - Li, J., Huo, H., Li, C., Wang, R., & Feng, Q. (2021). AttentionFGAN: Infrared and Visible Image Fusion Using Attention-Based Generative Adversarial Networks. IEEE Transactions on Multimedia, 23, 1383-1396.
[CrossRef] [Google Scholar] - Huang, S., Song, Z., Yang, Y., Wan, W., & Kong, X. (2023). MAGAN: Multiattention Generative Adversarial Network for Infrared and Visible Image Fusion. IEEE Transactions on Instrumentation and Measurement, 72, 1-14.
[CrossRef] [Google Scholar] - Fu, Y., Liu, Z., Peng, J., Gupta, R., & Zhang, D. (2025). GANSD: A generative adversarial network based on saliency detection for infrared and visible image fusion. Image and Vision Computing, 154, 105410.
[CrossRef] [Google Scholar] - Hu, X., Liu, Y., & Yang, F. (2024). PFCFuse: A Poolformer and CNN Fusion Network for Infrared-Visible Image Fusion. IEEE Transactions on Instrumentation and Measurement, 73, 1-14.
[CrossRef] [Google Scholar] - Lu, Q., Zhang, H., & Yin, L. (2025). Infrared and visible image fusion via dual encoder based on dense connection. Pattern Recognition, 163, 111476.
[CrossRef] [Google Scholar] - Wang, W., Deng, L.-J., Ran, R., & Vivone, G. (2024). A General Paradigm with Detail-Preserving Conditional Invertible Network for Image Fusion. International Journal of Computer Vision, 132(4), 1029–1054.
[CrossRef] [Google Scholar] - Liu, R., Jiang, Z., Yang, S., & Fan, X. (2022). Twin Adversarial Contrastive Learning for Underwater Image Enhancement and Beyond. IEEE Transactions on Image Processing, 31, 4922–4936.
[CrossRef] [Google Scholar] - Zheng, Y., Essock, E. A., Hansen, B. C., & Haun, A. M. (2007). A new metric based on extended spatial frequency and its application to DWT based fusion algorithms. Information Fusion, 8(2), 177-192.
[CrossRef] [Google Scholar] - Cui, G., Feng, H., Xu, Z., Li, Q., & Chen, Y. (2015). Detail preserved fusion of visible and infrared images using regional saliency extraction and multi-scale image decomposition. Optics Communications, 341, 199-209.
[CrossRef] [Google Scholar] - Tang, W., He, F., & Liu, Y. (2024). ITFuse: An interactive transformer for infrared and visible image fusion. Pattern Recognition, 156, 110822.
[CrossRef] [Google Scholar] - Qian, Y., Tang, H., Liu, G., Xing, M., Xiao, G., & Bavirisetti, D. P. (2024). LiMFusion: Infrared and visible image fusion via local information measurement. Optics and Lasers in Engineering, 181, 108435.
[CrossRef] [Google Scholar] - Li, X., Zhang, G., Cui, H., Hou, S., Wang, S., Li, X., Chen, Y., Li, Z., & Zhang, L. (2022). MCANet: A joint semantic segmentation framework of optical and SAR images for land use classification. International Journal of Applied Earth Observation and Geoinformation, 106, 102638.
[CrossRef] [Google Scholar] - Rottensteiner, F., Sohn, G., Jung, J., Gerke, M., Baillard, C., Bnitez, S., & Breitkopf, U. (2020). International society for photogrammetry and remote sensing, 2d semantic labeling contest. Accessed: Oct,29.
[Google Scholar] - Zhao, W., Cui, H., Wang, H., He, Y., & Lu, H. (2025). FreeFusion: Infrared and visible image fusion via cross reconstruction learning. IEEE Transactions on Pattern Analysis and Machine Intelligence, 47(9), 8040-8056.
[CrossRef] [Google Scholar]
Cited By (4)
-
Shaobing Gao, Minjie Tan, Shun Lv, Yiguang Liu, Yongjie Li. Infrared and Visible Image Fusion Using Bimodal Neuron and Dynamic Receptive Field Mechanisms.
IEEE Transactions on Image Processing, 2026 , 35 .
[CrossRef] -
Časlav Livada, Tomislav Galba, Alfonzo Baumgartner, Krešimir Nenadić. A Hybrid Chaotic Bat Algorithm With Deep Learning Optimization for Multi-Level Image Segmentation.
IEEE Access, 2026 , 14 .
[CrossRef] -
Lingxin Gongye, Shiyuan He, Jianhua Guo. Dual adaptive graph laplacian regularization for high-fidelity hyperspectral image fusion.
Information Fusion, 2026 , 133 .
[CrossRef] -
Jun Xie, Hua Huang, Lingfei Song. A Model-Free Method for Irregular Bias Field Correction in Infrared Images.
IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing, 2026 , 19 .
[CrossRef]
Cite This Article
TY  - JOUR
AU  - Qiu, Weitao
AU  - Zhao, Wenda
AU  - Wang, Haipeng
PY  - 2025
DA  - 2025/09/21
TI  - Self-supervised Segmentation Feature Alignment for Infrared and Visible Image Fusion
JO  - Chinese Journal of Information Fusion
T2  - Chinese Journal of Information Fusion
JF  - Chinese Journal of Information Fusion
VL  - 2
IS  - 3
SP  - 223
EP  - 236
DO  - 10.62762/CJIF.2025.822280
UR  - https://www.icck.org/article/abs/CJIF.2025.822280
KW  - image fusion
KW  - self-supervised segmentation feature alignment
KW  - feature interaction
KW  - deep learning
AB  - Existing deep learning-based methods for infrared and visible image fusion typically operate independently of other high-level vision tasks, overlooking the potential benefits these tasks could offer. For instance, semantic features from image segmentation could enrich the fusion results by providing detailed target information. However, segmentation focuses on target-level semantic feature information (e.g., object categories), while fusion focuses more on pixel-level detail feature information (e.g., local textures), creating a feature representation gap. To address this challenge, we propose a self-supervised segmentation feature alignment fusion network (SegFANet), which aligns target-level semantic features from segmentation tasks with pixel-level fusion features through self-supervised learning, thereby bridging the feature gap between the two tasks and improving the quality of image fusion. Extensive experiments on the WHU and Potsdam datasets show our method's effectiveness, outperforming the state-of-the-art methods.
SN  - 2998-3371
PB  - Institute of Central Computation and Knowledge
LA  - English
ER  -
@article{Qiu2025Selfsuperv,
  author = {Weitao Qiu and Wenda Zhao and Haipeng Wang},
  title = {Self-supervised Segmentation Feature Alignment for Infrared and Visible Image Fusion},
  journal = {Chinese Journal of Information Fusion},
  year = {2025},
  volume = {2},
  number = {3},
  pages = {223-236},
  doi = {10.62762/CJIF.2025.822280},
  url = {https://www.icck.org/article/abs/CJIF.2025.822280},
  abstract = {Existing deep learning-based methods for infrared and visible image fusion typically operate independently of other high-level vision tasks, overlooking the potential benefits these tasks could offer. For instance, semantic features from image segmentation could enrich the fusion results by providing detailed target information. However, segmentation focuses on target-level semantic feature information (e.g., object categories), while fusion focuses more on pixel-level detail feature information (e.g., local textures), creating a feature representation gap. To address this challenge, we propose a self-supervised segmentation feature alignment fusion network (SegFANet), which aligns target-level semantic features from segmentation tasks with pixel-level fusion features through self-supervised learning, thereby bridging the feature gap between the two tasks and improving the quality of image fusion. Extensive experiments on the WHU and Potsdam datasets show our method's effectiveness, outperforming the state-of-the-art methods.},
  keywords = {image fusion, self-supervised segmentation feature alignment, feature interaction, deep learning},
  issn = {2998-3371},
  publisher = {Institute of Central Computation and Knowledge}
}
Publisher's Note
ICCK stays neutral with regard to jurisdictional claims in published maps and institutional affiliations.
Rights and Permissions
 Copyright © 2025 by the Author(s). Published by Institute of Central Computation and Knowledge. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/), which permits use, sharing, adaptation, distribution and reproduction in any medium or format, as long as you give appropriate credit to the original author(s) and the source, provide a link to the Creative Commons licence, and indicate if changes were made.
Portico

