In-depth Urdu Sentiment Analysis Through Multilingual BERT and Supervised Learning Approaches

Article Information
Abstract
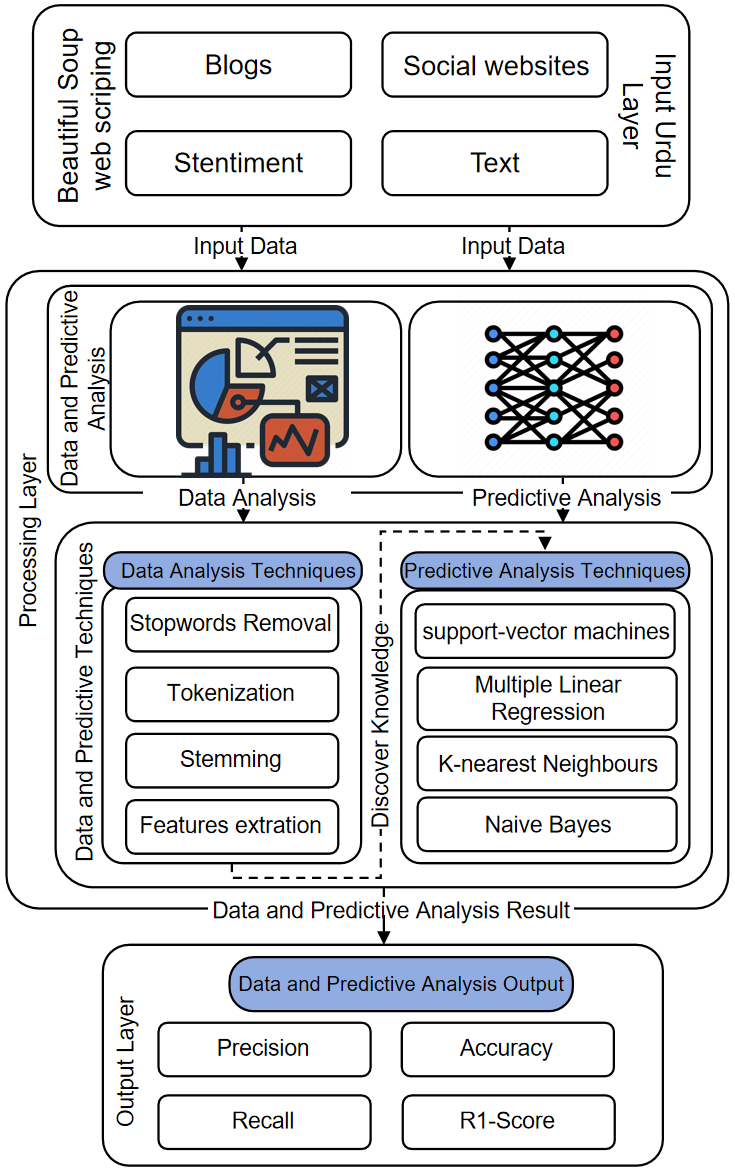
Sentiment analysis is a crucial component of intelligent information processing systems, enabling machines to understand and categorize human opinions expressed in text. While extensively studied for high-resource languages such as English and Chinese, it remains underexplored for low-resource languages like Urdu. This paper presents an intelligent multilingual sentiment analysis framework for Urdu text by integrating supervised machine learning techniques with a transformer-based model. We manually annotated and preprocessed a dataset collected from various Urdu blog websites, categorizing sentiments into positive, neutral, and negative classes. Four machine learning classifiers—Support Vector Machine (SVM), K-Nearest Neighbors (KNN), Naive Bayes, and Multinomial Logistic Regression (MLR)—along with the transformer-based multilingual BERT (mBERT) model were systematically evaluated. The mBERT model was fine-tuned to capture deep contextual embeddings tailored for Urdu, leveraging transfer learning from a model pre-trained on 104 languages. Experimental results demonstrate that the proposed intelligent framework significantly outperforms traditional classifiers, achieving an accuracy of 96.5% on the test set. This study highlights the effectiveness of transfer learning and deep contextual models in building robust intelligent systems for low-resource language processing, contributing to the advancement of inclusive and systematic intelligence in natural language understanding.
Graphical Abstract
Keywords
Data Availability Statement
Funding
Conflicts of Interest
Ethical Approval and Consent to Participate
References
- Mirza, A., Fayyaz, M., Seher, Z., & Siddiqi, I. (2018, March). Urdu caption text detection using textural features. In Proceedings of the 2nd Mediterranean Conference on Pattern Recognition and Artificial Intelligence (pp. 70-75).
[CrossRef] [Google Scholar] - Arafat, S. Y., & Iqbal, M. J. (2020). Urdu-text detection and recognition in natural scene images using deep learning. IEEE Access, 8, 96787-96803.
[CrossRef] [Google Scholar] - Farooq, A., Noreen, Z., Batool, S., & Naz, F. (2022, October). Urdu news classification: An empirical study using machine learning techniques. In 2022 Mohammad Ali Jinnah University International Conference on Computing (MAJICC) (pp. 1-7). IEEE.
[CrossRef] [Google Scholar] - Khan, M. B. (2021). Urdu news classification using application of machine learning algorithms on news headline. International Journal of Computer Science & Network Security, 21(2), 229-237.
[Google Scholar] - Shoaib, U., Fiaz, L., Chakraborty, C., & Rauf, H. T. (2023). Context-aware Urdu information retrieval system. ACM Transactions on Asian and Low-Resource Language Information Processing, 22(3), 1-19.
[CrossRef] [Google Scholar] - Hussain, R., Khan, H. A., Siddiqi, I., Khurshid, K., & Masood, A. (2015, November). Keyword based information retrieval system for Urdu document images. In 2015 11th International Conference on Signal-Image Technology & Internet-Based Systems (SITIS) (pp. 27-33). IEEE.
[CrossRef] [Google Scholar] - Rasheed, I., & Banka, H. (2018, March). Query expansion in information retrieval for Urdu language. In 2018 Fourth International Conference on Information Retrieval and Knowledge Management (CAMP) (pp. 1-6). IEEE.
[CrossRef] [Google Scholar] - Mukhtar, N., & Khan, M. A. (2018). Urdu sentiment analysis using supervised machine learning approach. International Journal of Pattern Recognition and Artificial Intelligence, 32(02), 1851001.
[CrossRef] [Google Scholar] - Rehman, Z. U., & Bajwa, I. S. (2016, August). Lexicon-based sentiment analysis for Urdu language. In 2016 sixth international conference on innovative computing technology (INTECH) (pp. 497-501). IEEE.
[CrossRef] [Google Scholar] - Liaqat, M. I., Hassan, M. A., Shoaib, M., Khurshid, S. K., & Shamseldin, M. A. (2022). Sentiment analysis techniques, challenges, and opportunities: Urdu language-based analytical study. PeerJ Computer Science, 8, e1032.
[CrossRef] [Google Scholar] - Ali, A. R., & Ijaz, M. (2009, December). Urdu text classification. In Proceedings of the 7th international conference on frontiers of information technology (pp. 1-7).
[CrossRef] [Google Scholar] - Mehmood, F., Shahzadi, R., Ghafoor, H., Asim, M. N., Ghani, M. U., Mahmood, W., & Dengel, A. (2023). EnML: Multi-label ensemble learning for Urdu text classification. ACM Transactions on Asian and Low-Resource Language Information Processing, 22(9), 1-31.
[CrossRef] [Google Scholar] - Roy, S., & Saini, J. R. (2023, August). A review of challenges in aspect-based sentiment analysis sub-tasks in resource-scarce indian languages. In 2023 7th International Conference On Computing, Communication, Control And Automation (ICCUBEA) (pp. 1-9). IEEE.
[CrossRef] [Google Scholar] - Mehmood, K., Essam, D., Shafi, K., & Malik, M. K. (2019). Discriminative feature spamming technique for roman urdu sentiment analysis. IEEE Access, 7, 47991-48002.
[CrossRef] [Google Scholar] - Asghar, M. Z., Sattar, A., Khan, A., Ali, A., Masud Kundi, F., & Ahmad, S. (2019). Creating sentiment lexicon for sentiment analysis in Urdu: The case of a resource‐poor language. Expert Systems, 36(3), e12397.
[CrossRef] [Google Scholar] - Mehmood, F., Ghani, M. U., Ibrahim, M. A., Shahzadi, R., Mahmood, W., & Asim, M. N. (2020). A precisely xtreme-multi channel hybrid approach for roman urdu sentiment analysis. IEEE Access, 8, 192740-192759.
[CrossRef] [Google Scholar] - Syed, A. Z., Aslam, M., & Martinez-Enriquez, A. M. (2010). Lexicon based sentiment analysis of Urdu text using SentiUnits. In Advances in Artificial Intelligence: 9th Mexican International Conference on Artificial Intelligence, MICAI 2010, Pachuca, Mexico, November 8-13, 2010, Proceedings, Part I 9 (pp. 32-43). Springer Berlin Heidelberg.
[CrossRef] [Google Scholar] - Safdar, Z., Bajwa, R. S., Hussain, S., Abdullah, H. B., Safdar, K., & Draz, U. (2020). The role of Roman Urdu in multilingual information retrieval: A regional study. The Journal of Academic Librarianship, 46(6), 102258.
[CrossRef] [Google Scholar] - Khan, I. U., Khan, A., Khan, W., Su’ud, M. M., Alam, M. M., Subhan, F., & Asghar, M. Z. (2021). A review of Urdu sentiment analysis with multilingual perspective: A case of Urdu and roman Urdu language. Computers, 11(1), 3.
[CrossRef] [Google Scholar] - Akhtar, M., Shoukat, R. S., & Rehman, S. U. (2023). A machine learning approach for Urdu text sentiment analysis. Mehran University Research Journal of Engineering & Technology, 42(2), 75-87.
[Google Scholar] - Khan, L., Amjad, A., Afaq, K. M., & Chang, H. T. (2022). Deep sentiment analysis using CNN-LSTM architecture of English and Roman Urdu text shared in social media. Applied Sciences, 12(5), 2694.
[CrossRef] [Google Scholar] - Ahmed, N., Amin, R., Aldabbas, H., Saeed, M., Bilal, M., & Song, H. (2024). A Novel Approach for Sentiment Analysis of a Low Resource Language Using Deep Learning Models. ACM Transactions on Asian and Low-Resource Language Information Processing.
[CrossRef] [Google Scholar] - Khalid, U., Hussain, A., Arshad, M. U., Shahzad, W., & Beg, M. O. (2021). Co-occurrences using Fasttext embeddings for word similarity tasks in Urdu. arXiv preprint arXiv:2102.10957.
[CrossRef] [Google Scholar] - Ashraf, M. R., Jana, Y., Umer, Q., Jaffar, M. A., Chung, S., & Ramay, W. Y. (2023). BERT-based sentiment analysis for low-resourced languages: A case study of Urdu language. IEEE Access, 11, 110245-110259.
[CrossRef] [Google Scholar] - Chandio, B. A., Imran, A. S., Bakhtyar, M., Daudpota, S. M., & Baber, J. (2022). Attention-based RU-BiLSTM sentiment analysis model for roman Urdu. Applied Sciences, 12(7), 3641.
[CrossRef] [Google Scholar] - Li, D., Ahmed, K., Zheng, Z., Mohsan, S. A. H., Alsharif, M. H., Hadjouni, M., ... & Mostafa, S. M. (2022). Roman Urdu sentiment analysis using transfer learning. Applied Sciences, 12(20), 10344.
[CrossRef] [Google Scholar] - Khan, L., Amjad, A., Ashraf, N., Chang, H. T., & Gelbukh, A. (2021). Urdu sentiment analysis with deep learning methods. IEEE access, 9, 97803-97812.
[CrossRef] [Google Scholar] - Asim, M. N., Ghani, M. U., Ibrahim, M. A., Mahmood, W., Dengel, A., & Ahmed, S. (2021). Benchmarking performance of machine and deep learning-based methodologies for Urdu text document classification. Neural Computing and Applications, 33(11), 5437-5469.
[CrossRef] [Google Scholar] - Khan, L., Amjad, A., Ashraf, N., & Chang, H. T. (2022). Multi-class sentiment analysis of urdu text using multilingual BERT. Scientific Reports, 12(1), 5436.
[CrossRef] [Google Scholar] - Ahmed, K., Nadeem, M. I., Li, D., Zheng, Z., Al-Kahtani, N., Alkahtani, H. K., ... & Mamyrbayev, O. (2023). Contextually enriched meta-learning ensemble model for Urdu sentiment analysis. Symmetry, 15(3), 645.
[CrossRef] [Google Scholar] - Sehar, U., Kanwal, S., Dashtipur, K., Mir, U., Abbasi, U., & Khan, F. (2021). Urdu sentiment analysis via multimodal data mining based on deep learning algorithms. IEEE Access, 9, 153072-153082.
[CrossRef] [Google Scholar] - Mehmood, K., Essam, D., Shafi, K., & Malik, M. K. (2019). Sentiment analysis for a resource poor language—Roman Urdu. ACM Transactions on Asian and Low-Resource Language Information Processing (TALLIP), 19(1), 1-15.
[CrossRef] [Google Scholar] - Ul Hassan, M. N., Yu, Z., Wang, J., Li, Y., Gao, S., Yang, S., & Mao, C. (2024). LKMT: Linguistics Knowledge-Driven Multi-Task Neural Machine Translation for Urdu and English. Computers, Materials & Continua, 81(1).
[CrossRef] [Google Scholar] - Nasim, Z., & Ghani, S. (2020). Sentiment analysis on Urdu tweets using Markov chains. SN Computer Science, 1(5), 269.
[CrossRef] [Google Scholar] - Mukhtar, N., Khan, M. A., Chiragh, N., & Nazir, S. (2018). Identification and handling of intensifiers for enhancing accuracy of Urdu sentiment analysis. Expert Systems, 35(6), e12317.
[CrossRef] [Google Scholar] - Mukhtar, N., & Khan, M. A. (2020). Effective lexicon-based approach for Urdu sentiment analysis. Artificial Intelligence Review, 53(4), 2521-2548.
[CrossRef] [Google Scholar] - Khan, K., Khan, W., Rahman, A. U., Khan, A., Khan, A., Khan, A. U., & Saqia, B. (2018). Urdu sentiment analysis. International Journal of Advanced Computer Science and Applications, 9(9).
[CrossRef] [Google Scholar] - ul Mustafa, F., Ashraf, I., Baqir, A., Ahmad, U., Malik, S., & Mehmood, S. (2020, October). Prediction of user’s interest based on urdu tweets. In 2020 International Symposium on Recent Advances in Electrical Engineering & Computer Sciences (RAEE & CS) (Vol. 5, pp. 1-6). IEEE.
[CrossRef] [Google Scholar]
Cite This Article
TY  - JOUR
AU  - Saeed, Muhammad
AU  - Ahmed, Naeem
AU  - Ali, Danish
AU  - Ramzan, Muhammad
AU  - Mohib, Muzamil
AU  - Bagga, Kajol
AU  - Rahman, Atif Ur
AU  - Khan, Ikram Majeed
PY  - 2024
DA  - 2024/11/09
TI  - In-depth Urdu Sentiment Analysis Through Multilingual BERT and Supervised Learning Approaches
JO  - ICCK Transactions on Intelligent Systematics
T2  - ICCK Transactions on Intelligent Systematics
JF  - ICCK Transactions on Intelligent Systematics
VL  - 1
IS  - 3
SP  - 161
EP  - 175
DO  - 10.62762/TIS.2024.585616
UR  - https://www.icck.org/article/abs/TIS.2024.585616
KW  - machine learning
KW  - sentiment analysis
KW  - Urdu language
KW  - natural language processing (NLP)
KW  - intelligent systems
AB  - Sentiment analysis is a crucial component of intelligent information processing systems, enabling machines to understand and categorize human opinions expressed in text. While extensively studied for high-resource languages such as English and Chinese, it remains underexplored for low-resource languages like Urdu. This paper presents an intelligent multilingual sentiment analysis framework for Urdu text by integrating supervised machine learning techniques with a transformer-based model. We manually annotated and preprocessed a dataset collected from various Urdu blog websites, categorizing sentiments into positive, neutral, and negative classes. Four machine learning classifiers—Support Vector Machine (SVM), K-Nearest Neighbors (KNN), Naive Bayes, and Multinomial Logistic Regression (MLR)—along with the transformer-based multilingual BERT (mBERT) model were systematically evaluated. The mBERT model was fine-tuned to capture deep contextual embeddings tailored for Urdu, leveraging transfer learning from a model pre-trained on 104 languages. Experimental results demonstrate that the proposed intelligent framework significantly outperforms traditional classifiers, achieving an accuracy of 96.5% on the test set. This study highlights the effectiveness of transfer learning and deep contextual models in building robust intelligent systems for low-resource language processing, contributing to the advancement of inclusive and systematic intelligence in natural language understanding.
SN  - 3068-5079
PB  - Institute of Central Computation and Knowledge
LA  - English
ER  -
@article{Saeed2024Indepth,
  author = {Muhammad Saeed and Naeem Ahmed and Danish Ali and Muhammad Ramzan and Muzamil Mohib and Kajol Bagga and Atif Ur Rahman and Ikram Majeed Khan},
  title = {In-depth Urdu Sentiment Analysis Through Multilingual BERT and Supervised Learning Approaches},
  journal = {ICCK Transactions on Intelligent Systematics},
  year = {2024},
  volume = {1},
  number = {3},
  pages = {161-175},
  doi = {10.62762/TIS.2024.585616},
  url = {https://www.icck.org/article/abs/TIS.2024.585616},
  abstract = {Sentiment analysis is a crucial component of intelligent information processing systems, enabling machines to understand and categorize human opinions expressed in text. While extensively studied for high-resource languages such as English and Chinese, it remains underexplored for low-resource languages like Urdu. This paper presents an intelligent multilingual sentiment analysis framework for Urdu text by integrating supervised machine learning techniques with a transformer-based model. We manually annotated and preprocessed a dataset collected from various Urdu blog websites, categorizing sentiments into positive, neutral, and negative classes. Four machine learning classifiers—Support Vector Machine (SVM), K-Nearest Neighbors (KNN), Naive Bayes, and Multinomial Logistic Regression (MLR)—along with the transformer-based multilingual BERT (mBERT) model were systematically evaluated. The mBERT model was fine-tuned to capture deep contextual embeddings tailored for Urdu, leveraging transfer learning from a model pre-trained on 104 languages. Experimental results demonstrate that the proposed intelligent framework significantly outperforms traditional classifiers, achieving an accuracy of 96.5\% on the test set. This study highlights the effectiveness of transfer learning and deep contextual models in building robust intelligent systems for low-resource language processing, contributing to the advancement of inclusive and systematic intelligence in natural language understanding.},
  keywords = {machine learning, sentiment analysis, Urdu language, natural language processing (NLP), intelligent systems},
  issn = {3068-5079},
  publisher = {Institute of Central Computation and Knowledge}
}
Publisher's Note
ICCK stays neutral with regard to jurisdictional claims in published maps and institutional affiliations.
Rights and Permissions
Portico