Adaptive Learning Density Estimators for Tsallis Entropy and Kapur Entropy with Applications in System Training

Article Information
Abstract
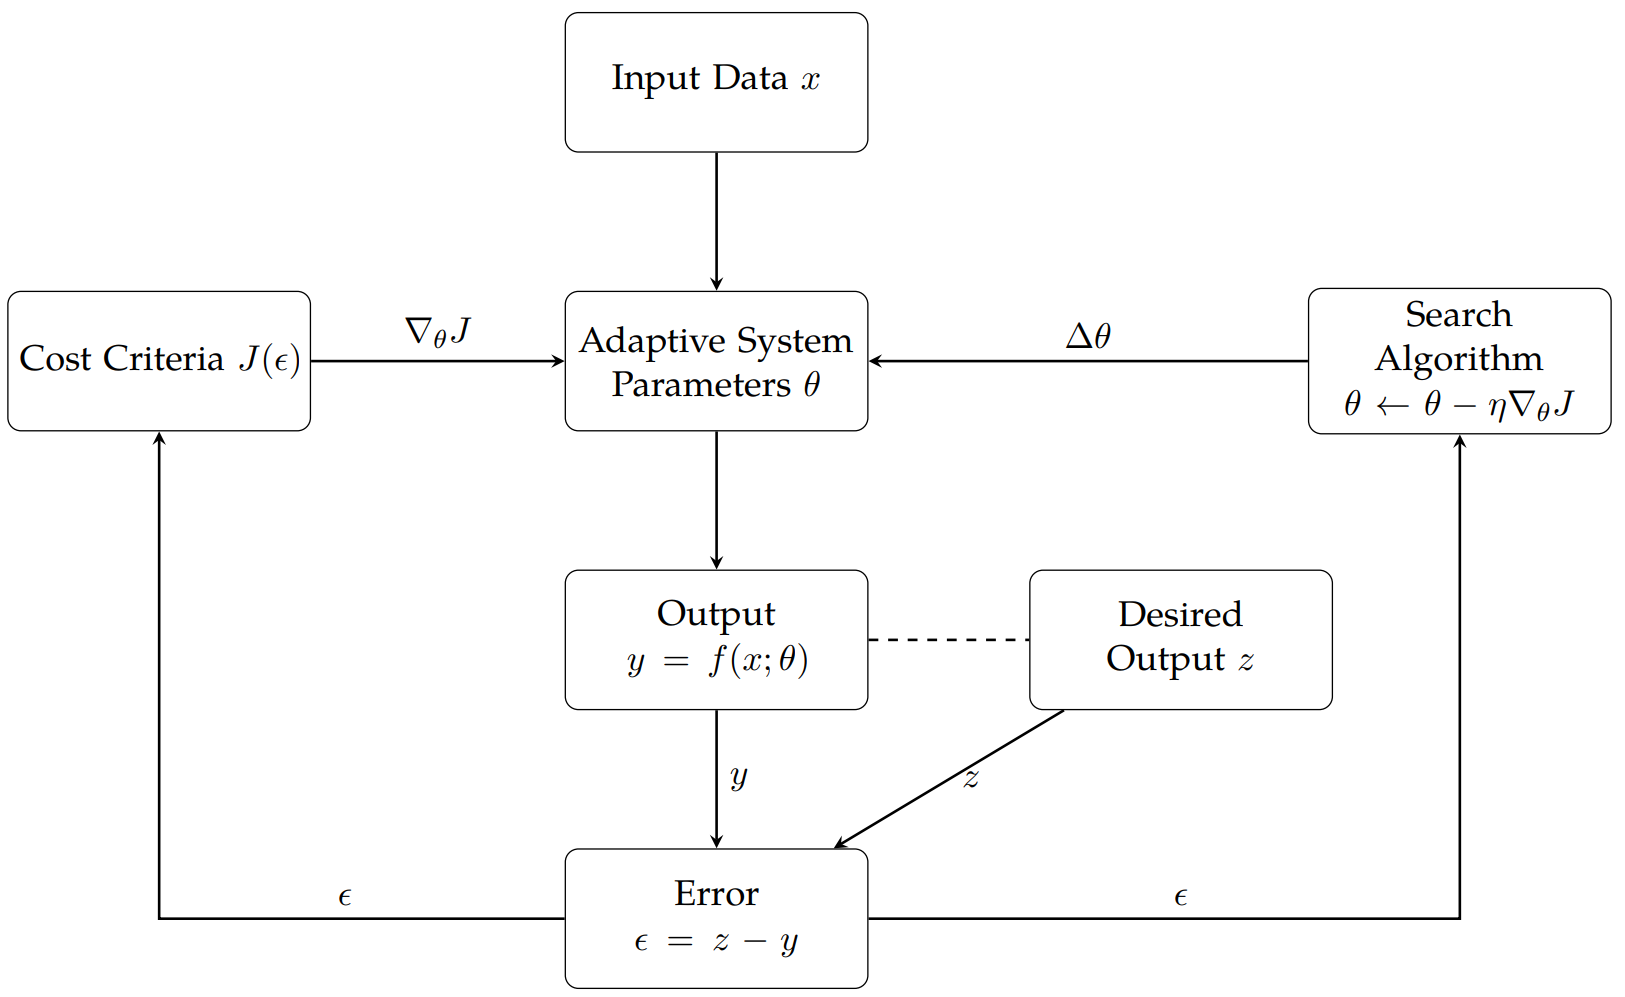
Adaptation learning is a data-driven technique that adjusts its behavior based on the experience gained during data analysis. It plays an integral role in providing engineering solutions based on specific needs. Researchers have used the second-order statistics criterion for decades to conceptualize the optimality criteria using Shannon's and Rényi’s information-theoretic measures. Some gaps have been identified in this research work, and useful findings have been established using generalized information-theoretic measures, namely Tsallis entropy of order $\alpha$ and Kapur entropy of order $\alpha$ and type $\beta$, via the Parzen--Rosenblatt window. This work explores the problem of constructing kernel density estimators and their application in adaptive systems training.
Graphical Abstract
Keywords
Data Availability Statement
Funding
Conflicts of Interest
AI Use Statement
Ethical Approval and Consent to Participate
References
- Wiener, N. (1949). Extrapolation, interpolation, and smoothing of stationary time series: with engineering applications. The MIT press.
[CrossRef] [Google Scholar] - Shannon, C. E. (1948). A mathematical theory of communication. The Bell system technical journal, 27(3), 379-423.
[CrossRef] [Google Scholar] - Rényi, A. (1961, January). On measures of entropy and information. In Proceedings of the fourth Berkeley symposium on mathematical statistics and probability, volume 1: contributions to the theory of statistics (Vol. 1, pp. 547-562). University of California Press.
[Google Scholar] - Tsallis, C. (1988). Possible generalization of Boltzmann-Gibbs statistics. Journal of statistical physics, 52(1), 479-487.
[CrossRef] [Google Scholar] - Kapur, J. N. (1969, April). Some properties of entropy of order $\alpha$ and type $\beta$. In Proceedings of the Indian Academy of Sciences-Section A (Vol. 69, No. 4, pp. 201-211). New Delhi: Springer India.
[CrossRef] [Google Scholar] - Barlow, H. B., Kaushal, T. P., & Mitchison, G. J. (1989). Finding minimum entropy codes. Neural computation, 1(3), 412-423.
[CrossRef] [Google Scholar] - Erdogmus, D., & Principe, J. C. (2002). An error-entropy minimization algorithm for supervised training of nonlinear adaptive systems. IEEE Transactions on Signal Processing, 50(7), 1780-1786.
[CrossRef] [Google Scholar] - Erdogmus, D., & Principe, J. C. (2003). Convergence properties and data efficiency of the minimum error entropy criterion in adaline training. IEEE Transactions on Signal Processing, 51(7), 1966-1978.
[CrossRef] [Google Scholar] - Martí, A., de Cabrera, F., & Riba, J. (2023). On the estimation of Tsallis entropy and a novel information measure based on its properties. IEEE Signal Processing Letters, 30, 818-822.
[CrossRef] [Google Scholar] - Lazo, A. V., & Rathie, P. (1978). On the entropy of continuous probability distributions (corresp.). IEEE Transactions on Information Theory, 24(1), 120-122.
[CrossRef] [Google Scholar] - Ahmed, N. A., & Gokhale, D. V. (1989). Entropy expressions and their estimators for multivariate distributions. IEEE Transactions on Information Theory, 35(3), 688-692.
[CrossRef] [Google Scholar] - Havrda, J., & Charvat, F. (1967). Quantification method of classification processes. Concept of structural $\alpha$-entropy. Kybernetika, 3(1), 30-35. https://dml.cz/handle/10338.dmlcz/125526
[Google Scholar] - Kapur, J. N. (1994). Measures of information and their applications. Wiley. Retrieved from https://cir.nii.ac.jp/crid/1971430859819604036 (accessed on 05 January 2026).
[Google Scholar] - Principe, J. C., Xu, D., Zhao, Q., & Fisher III, J. W. (2000). Learning from examples with information theoretic criteria. Journal of VLSI signal processing systems for signal, image and video technology, 26(1), 61-77.
[CrossRef] [Google Scholar] - Chen, B., Zhu, Y., & Hu, J. (2010). Mean-square convergence analysis of ADALINE training with minimum error entropy criterion. IEEE transactions on neural networks, 21(7), 1168-1179.
[CrossRef] [Google Scholar] - Santamaría, I., Erdogmus, D., & Principe, J. C. (2002). Entropy minimization for supervised digital communications channel equalization. IEEE Transactions on Signal Processing, 50(5), 1184-1192.
[CrossRef] [Google Scholar] - Irshad, M. R., Maya, R., Buono, F., & Longobardi, M. (2021). Kernel estimation of cumulative residual Tsallis entropy and its dynamic version under $\rho$-mixing dependent data. Entropy, 24(1), 9.
[CrossRef] [Google Scholar] - Bassat, M. B., & Raviv, J. (1978). Renyi's entropy and the probability of error. IEEE Transactions on Information Theory, 24(3), 324-331.
[CrossRef] [Google Scholar] - Erdogmus, D., & Principe, J. C. (2002). Generalized information potential criterion for adaptive system training. IEEE Transactions on Neural Networks, 13(5), 1035-1044.
[CrossRef] [Google Scholar] - Principe, J. C. (2010). Information theoretic learning: Renyi's entropy and kernel perspectives. Springer Science & Business Media.
[CrossRef] [Google Scholar] - Xu, D. (1998). Energy, entropy and information potential for neural computation. University of Florida.
[Google Scholar] - Bowman, A. W., & Azzalini, A. (1997). Applied smoothing techniques for data analysis: the kernel approach with S-Plus illustrations (Vol. 18). OUP Oxford.
[Google Scholar] - Scott, D. W. (1992). Multivariate density estimation: theory, practice, and visualization. John Wiley & Sons.
[CrossRef] [Google Scholar] - Silverman, B. W. (2018). Density estimation for statistics and data analysis. Routledge.
[CrossRef] [Google Scholar] - Härdle, W., Werwatz, A., Müller, M., & Sperlich, S. (2004). Nonparametric and semiparametric models. Springer.
[CrossRef] [Google Scholar] - Horová, I., Koláček, J., & Zelinka, J. (2012). Kernel Smoothing in MATLAB: theory and practice of kernel smoothing. World scientific.
[CrossRef] [Google Scholar] - Devroye, L., & Krzyzak, A. (1999). On the Hilbert kernel density estimate. Statistics & Probability Letters, 44(3), 299-308.
[CrossRef] [Google Scholar] - Duong, T., & Hazelton, M. L. (2008). Feature significance for multivariate kernel density estimation. Computational Statistics & Data Analysis, 52(9), 4225-4242.
[CrossRef] [Google Scholar] - Lake, D. E. (2009). Nonparametric entropy estimation using kernel densities. Methods in enzymology, 467, 531-546.
[CrossRef] [Google Scholar] - Gyorfi, L., & Van der Meulen, E. C. (1991). On the nonparametric estimation of the entropy functional. In G. Roussas (Ed.), Nonparametric Functional Estimation and Related Topics (pp. 81-95). Springer.
[CrossRef] [Google Scholar] - Chen, B., Yuan, Z., Zheng, N., & Príncipe, J. C. (2013). Kernel minimum error entropy algorithm. Neurocomputing, 121, 160-169.
[CrossRef] [Google Scholar] - Beirlant, J., Dudewicz, E. J., Gyorfi, L., & Van der Meulen, E. C. (1997). Nonparametric entropy estimation: An overview. International Journal of Mathematical and Statistical Sciences, 6(1), 17-39. https://jimbeck.caltech.edu/summerlectures/references/Entropy%20estimation.pdf
[Google Scholar] - Ahmad, I., & Lin, P. E. (1976). A nonparametric estimation of the entropy for absolutely continuous distributions. IEEE Transactions on Information Theory, 22(3), 372-375.
[CrossRef] [Google Scholar] - Gokcay, E., & Principe, J. C. (2002). Information theoretic clustering. IEEE transactions on pattern analysis and machine intelligence, 24(2), 158-171.
[CrossRef] [Google Scholar] - Parzen, E. (1962). On estimation of a probability density function and mode. The Annals of Mathematical Statistics, 33(3), 1065-1076. https://www.jstor.org/stable/2237880
[Google Scholar] - Loftsgaarden, D. O., & Quesenberry, C. P. (1965). A nonparametric estimate of a multivariate density function. The Annals of Mathematical Statistics, 36(3), 1049-1051.
[CrossRef] [Google Scholar] - Breiman, L., Meisel, W., & Purcell, E. (1977). Variable kernel estimates of multivariate densities. Technometrics, 19(2), 135-144. https://www.tandfonline.com/doi/abs/10.1080/00401706.1977.10489521
[Google Scholar] - Davis, R. A., Lii, K. S., & Politis, D. N. (2011). Remarks on some nonparametric estimates of a density function. In Selected Works of Murray Rosenblatt (pp. 95-100). New York, NY: Springer New York.
[CrossRef] [Google Scholar] - Hardle, W. (1991). Smoothing techniques: With implementation in S. Springer.
[CrossRef] [Google Scholar] - Hall, P., Hu, T. C., & Marron, J. S. (1995). Improved variable window kernel estimates of probability densities. The Annals of Statistics, 23(1), 1-10. https://www.jstor.org/stable/2242395
[Google Scholar] - Wand, M. P., & Jones, M. C. (1994). Kernel smoothing. CRC Press.
[Google Scholar] - Stute, W. (1982). A law of the logarithm for kernel density estimators. The Annals of Probability, 10(2), 414-422. https://www.jstor.org/stable/2243439
[Google Scholar] - Stute, W. (1982). The oscillation behavior of empirical processes. The Annals of Probability, 10(1), 86-107. https://www.jstor.org/stable/2243773
[Google Scholar] - Einmahl, U., & Mason, D. M. (2005). Uniform in bandwidth consistency of kernel-type function estimators. The Annals of Statistics, 33(3), 1380-1403.
[CrossRef] [Google Scholar] - Wied, D., & Weibbach, R. (2012). Consistency of the kernel density estimator: A survey. Statistical Papers, 53(1), 1-21.
[CrossRef] [Google Scholar] - Nadaraja, E. A. (1965). On non-parametric estimates of density functions and regression curves. Theory of Probability & Its Applications, 10(1), 186-190.
[CrossRef] [Google Scholar] - Erdogmus, D., & Principe, J. C. (2001, September). Convergence analysis of the information potential criterion in adaline training. In Neural Networks for Signal Processing XI: Proceedings of the 2001 IEEE Signal Processing Society Workshop (IEEE Cat. No. 01TH8584) (pp. 123-132). IEEE.
[CrossRef] [Google Scholar] - Erdogmus, D., & Principe, J. C. (2001). An on-line adaptation algorithm for adaptive system training with minimum error entropy: Stochastic information gradient. In Proceedings of the 2001 International Conference on Independent Component Analysis and Signal Separation (pp. 7-12). https://www1.ece.neu.edu/~erdogmus/publications/C008_ICA2001_SIG.pdf
[Google Scholar]
Cited By (4)
-
İlknur Dönmez, Faruk Bulut. Multidimensional diversity in video recommender systems: a holistic framework of literature gaps and future directions.
Intelligent Systems with Applications, 2026 , 31 .
[CrossRef] -
Yingying Jiao. Research on an interactive film and entertainment style generation system based on multimodal input and AI models.
Entertainment Computing, 2026 , 57 .
[CrossRef] -
Shubhani Aggarwal, Arzoo Miglani, Norah Saleh Alghamdi, Gaurav Dhiman. Resilient and decentralized demand-side management in smart grids using blockchain.
Scientific Reports, 2026 , 16 (1).
[CrossRef] -
Gaurav Dhiman, Kiran Deep Singh, Prabh Deep Singh, Norah Saleh Alghamdi, Ghadah Shukri Albakri. A novel approach to reliable and flexible distributed computing with virtualization in smart healthcare applications.
Scientific Reports, 2026 , 16 (1).
[CrossRef]
Cite This Article
TY  - JOUR
AU  - Kumar, Vijay
AU  - Saxena, Arti
AU  - Chawla, Leena
PY  - 2026
DA  - 2026/01/06
TI  - Adaptive Learning Density Estimators for Tsallis Entropy and Kapur Entropy with Applications in System Training
JO  - ICCK Transactions on Machine Intelligence
T2  - ICCK Transactions on Machine Intelligence
JF  - ICCK Transactions on Machine Intelligence
VL  - 2
IS  - 1
SP  - 12
EP  - 27
DO  - 10.62762/TMI.2025.317970
UR  - https://www.icck.org/article/abs/TMI.2025.317970
KW  - generalized entropies
KW  - adaptive learning
KW  - machine learning
KW  - kernel density estimation
KW  - information theoretic measures
AB  - Adaptation learning is a data-driven technique that adjusts its behavior based on the experience gained during data analysis. It plays an integral role in providing engineering solutions based on specific needs. Researchers have used the second-order statistics criterion for decades to conceptualize the optimality criteria using Shannon's and Rényi’s information-theoretic measures. Some gaps have been identified in this research work, and useful findings have been established using generalized information-theoretic measures, namely Tsallis entropy of order $\alpha$ and Kapur entropy of order $\alpha$ and type $\beta$, via the Parzen--Rosenblatt window. This work explores the problem of constructing kernel density estimators and their application in adaptive systems training.
SN  - 3068-7403
PB  - Institute of Central Computation and Knowledge
LA  - English
ER  -
@article{Kumar2026Adaptive,
  author = {Vijay Kumar and Arti Saxena and Leena Chawla},
  title = {Adaptive Learning Density Estimators for Tsallis Entropy and Kapur Entropy with Applications in System Training},
  journal = {ICCK Transactions on Machine Intelligence},
  year = {2026},
  volume = {2},
  number = {1},
  pages = {12-27},
  doi = {10.62762/TMI.2025.317970},
  url = {https://www.icck.org/article/abs/TMI.2025.317970},
  abstract = {Adaptation learning is a data-driven technique that adjusts its behavior based on the experience gained during data analysis. It plays an integral role in providing engineering solutions based on specific needs. Researchers have used the second-order statistics criterion for decades to conceptualize the optimality criteria using Shannon's and Rényi’s information-theoretic measures. Some gaps have been identified in this research work, and useful findings have been established using generalized information-theoretic measures, namely Tsallis entropy of order \$\alpha\$ and Kapur entropy of order \$\alpha\$ and type \$\beta\$, via the Parzen--Rosenblatt window. This work explores the problem of constructing kernel density estimators and their application in adaptive systems training.},
  keywords = {generalized entropies, adaptive learning, machine learning, kernel density estimation, information theoretic measures},
  issn = {3068-7403},
  publisher = {Institute of Central Computation and Knowledge}
}
Publisher's Note
ICCK stays neutral with regard to jurisdictional claims in published maps and institutional affiliations.
Rights and Permissions
Portico
